Merging
Before you start: table selection; function calls and returned values.
Setup: No input files are needed. Build the example tables on this page before modifying them.
Your check: Specify keys and check duplicate matches and unmatched observations. Practise in the unit summary.
merge() combines data frames by matching values in key columns, regardless of row order. We will use the following two data frames; run the code blocks in order:
df1 <- data.frame(
  X = 1:5,
  Y = c(1.4, 2.5, 3.6, 4.0, 5.5),
  Z = c("A", "B", "C", "D", "E")
)
df2 <- data.frame(
  X = c(100, 200, 300, 400, 500),
  Y = c(14, 25, 36, 40, 55),
  Z = c("A", "C", "E", "D", "B")
)
Without a by argument, merge() uses every column name shared by both data frames as a key. Here, those names are X, Y, and Z. Although the Z values match, no row has matching values in all three columns, so this call returns zero rows:
merge(df1, df2)
To match on the identifiers in Z, specify that column explicitly:
dfc <- merge(df1, df2, by = "Z")
dfc
  Z X.x Y.x X.y Y.y
1 A   1 1.4 100  14
2 B   2 2.5 500  55
3 C   3 3.6 200  25
4 D   4 4.0 400  40
5 E   5 5.5 300  36
Both inputs also have columns named X and Y. In the result, .x marks a column from the first input (df1), and .y marks one from the second (df2). These suffixes refer to the inputs, not to the columns named X and Y.
If the key columns have different names, use by.x for the first input and by.y for the second. Here we rename a copy of df2, so df2 remains available for the earlier example:
df2_renamed <- df2
names(df2_renamed) <- c("H", "I", "J")
dfc <- merge(df1, df2_renamed, by.x = "Z", by.y = "J")
dfc
  Z X   Y   H  I
1 A 1 1.4 100 14
2 B 2 2.5 500 55
3 C 3 3.6 200 25
4 D 4 4.0 400 40
5 E 5 5.5 300 36
The key from the first input (Z) appears once in the result. The remaining names differ across the inputs, so R does not need .x or .y suffixes.
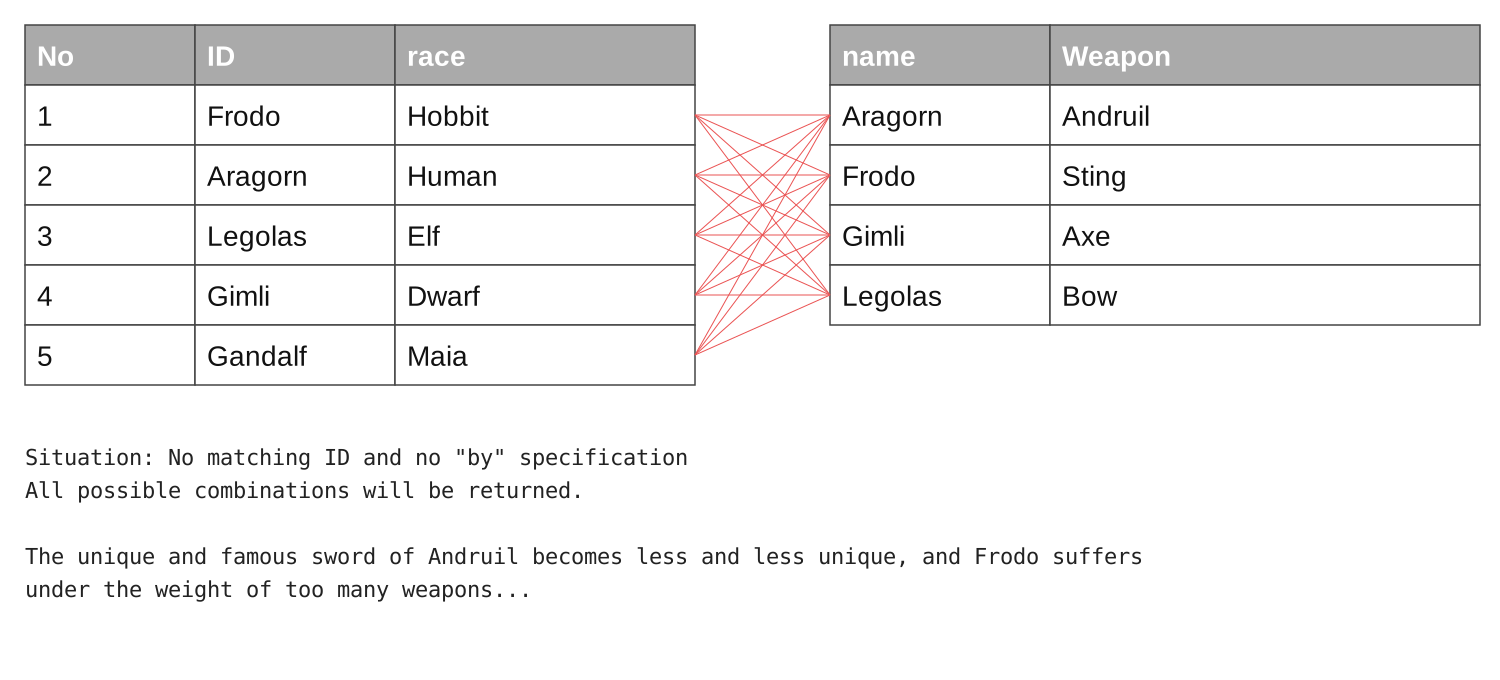
If the inputs have no column names in common, the default key is empty. merge() then produces a Cartesian product: every row of the first input is paired with every row of the second. For example, these two-row tables produce four rows:
left <- data.frame(site = c("A", "B"), height = c(10, 20))
right <- data.frame(habitat = c("forest", "grassland"))
merge(left, right)
The following illustration also shows all row combinations when there is no shared column name:
Check whether your intended key is unique in each input. When a key value occurs more than once on both sides, merge() returns every matching pair. Here, site A has two visits and two samples, producing four rows for A and one for B:
visits <- data.frame(site = c("A", "A", "B"), visit = c(1, 2, 1))
samples <- data.frame(site = c("A", "A", "B"), sample = c("soil", "water", "soil"))
anyDuplicated(visits$site) > 0
anyDuplicated(samples$site) > 0
merge(visits, samples, by = "site")
Both checks return TRUE, and the merged table has five rows. If you expected one row per site, determine which observations belong together or choose a more specific key before merging.
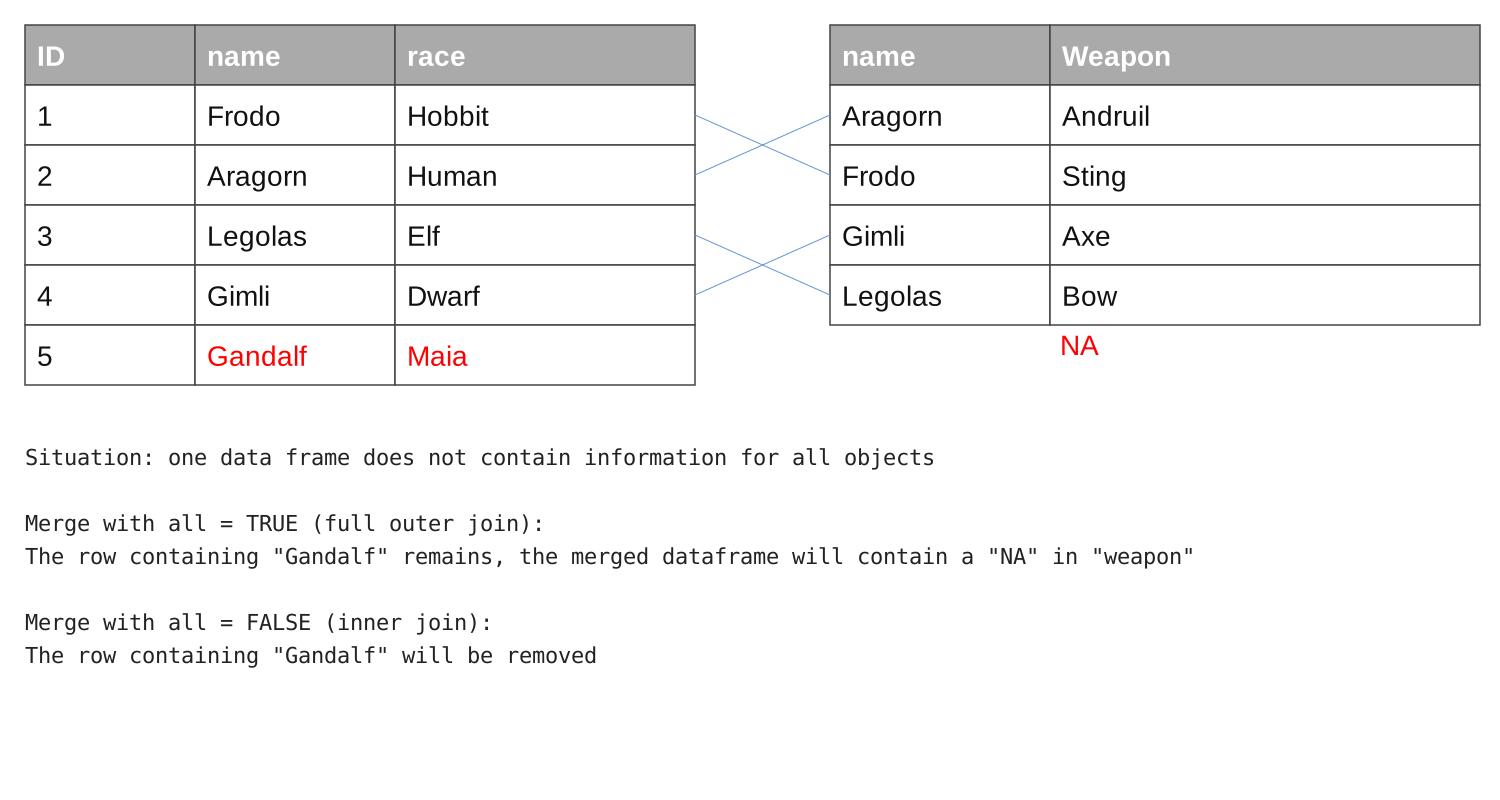
When you merge on a key, merge() keeps only rows whose key values match in both inputs by default. Use all = TRUE to retain unmatched rows from both inputs, all.x = TRUE for all rows from the first input, or all.y = TRUE for all rows from the second. Unmatched columns contain NA; Unit 04 explains how to find and handle missing values. The illustration below shows matching by the shared name column and what happens to unmatched rows when they are retained:
See the R documentation for merge() for the complete argument list and matching rules.