Example: Cross-Validation
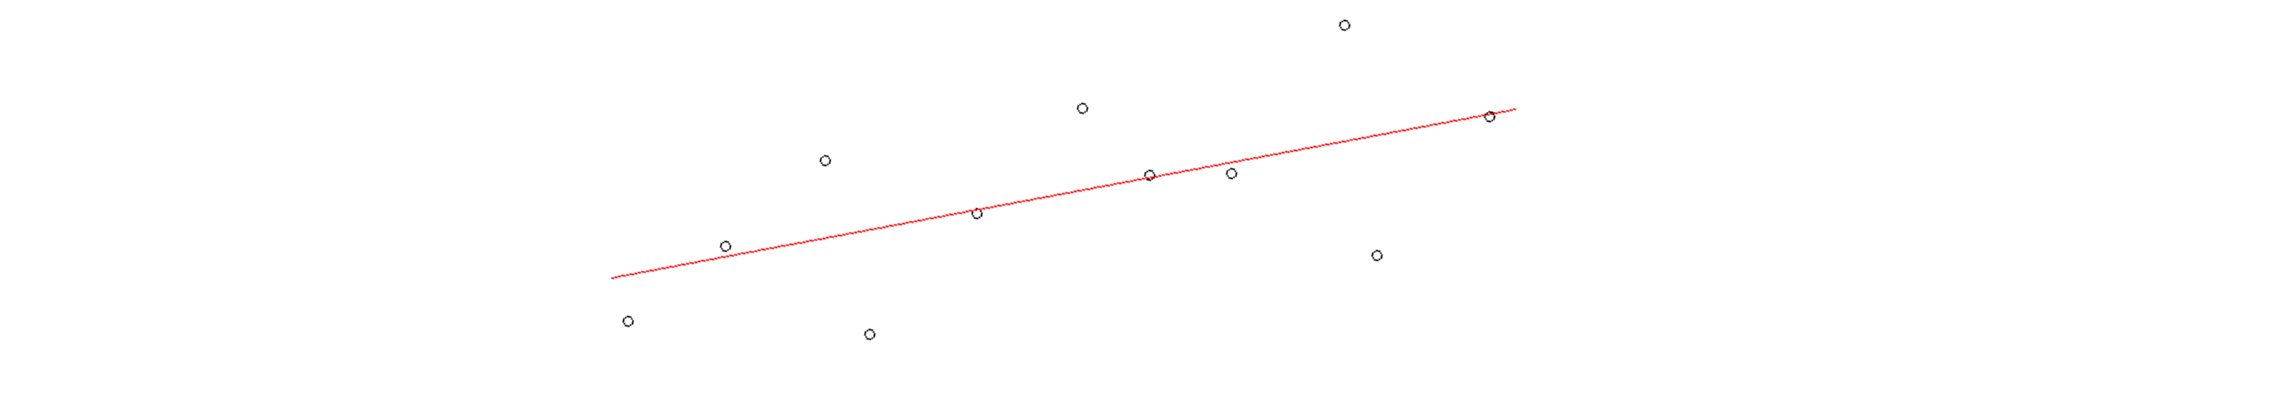
In Unit 05, we fitted a model and inspected its residuals. Here we ask: how well does it predict observations left out of fitting? We can measure those prediction errors even if the earlier diagnostics raised concerns; cross-validation does not make those concerns disappear.
Training observations are used to fit the model. Validation observations are left out of fitting and used to check its predictions. Cross-validation repeats this separation. We will use three approaches:
- Leave-one-out: hold out one observation at a time, until every observation has a prediction from a model fitted without it.
- Repeated random holdout: repeatedly choose a training sample and predict the remaining observations.
- Four-fold cross-validation: divide the observations into four groups, called folds. Hold out each fold once and fit on the other three.
We reuse x1 and y1 from the Anscombe dataset. These eleven observations make the steps easy to inspect, but give unstable performance estimates. First, recall the model fitted to all observations:
lmod <- lm(y1 ~ x1, data = anscombe)
plot(anscombe$x1, anscombe$y1)
abline(lmod, col = "red")
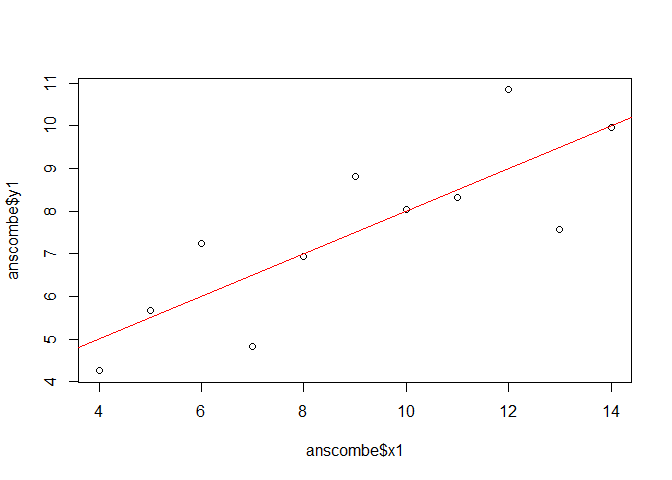
summary(lmod)$r.squared
## [1] 0.6665425
This R squared describes the fit to the training observations. We will assess held-out prediction error separately.
Leave-one-out cross-validation
Start with one observation, row 1. Fit without it, then predict its response. newdata supplies the held-out rows and must contain the predictor column named in the model (x1). Use the held-out response y1 only afterward to calculate the error.
i <- 1
train <- anscombe[-i, ]
validation <- anscombe[i, ]
model <- lm(y1 ~ x1, data = train)
predicted <- predict(model, newdata = validation)
validation$y1 - predicted
##          1
## 0.04333333
The prediction error is observed minus predicted: a positive error means underprediction. This follows the same sign convention as the residuals in Unit 05, but uses an observation left out of fitting.
Now repeat the fit and prediction for every row. unlist() turns the list of predictions into a vector, in the same row order as the observations:
predicted <- unlist(lapply(1:nrow(anscombe), function(i) {
  model <- lm(y1 ~ x1, data = anscombe[-i, ])
  predict(model, newdata = anscombe[i, ])
}))
Root mean squared error (RMSE) summarizes the size of the errors: square them, take their mean, then take the square root. RMSE has the response’s units and gives greater weight to large errors. Smaller RMSE means smaller errors on these held-out observations.
error <- anscombe$y1 - predicted
sqrt(mean(error^2))
## [1] 1.367787
Compare the held-out predictions with the observations. The diagonal indicates perfect prediction:
plot(anscombe$y1, predicted, xlab = "Observed response",
     ylab = "Held-out prediction", asp = 1)
abline(0, 1, col = "red")
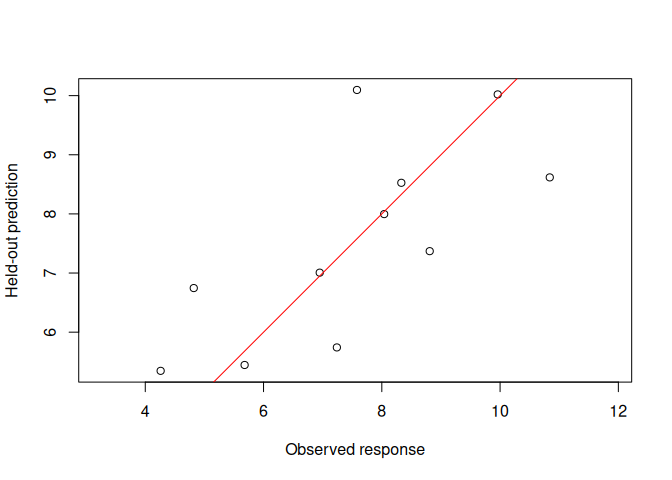
Take home: one complete leave-one-out run gives eleven held-out predictions and one RMSE.
Leave-many-out cross-validation
One complete holdout run
Hold out several observations together. For this first calculation, use rows 1–8 for training and the remaining three for validation. We will choose random training rows when we repeat the procedure.
train_rows <- 1:8
train <- anscombe[train_rows, ]
validation <- anscombe[-train_rows, ]
model <- lm(y1 ~ x1, data = train)
predicted <- predict(model, newdata = validation)
error <- validation$y1 - predicted
sqrt(mean(error^2))
## [1] 1.650601
The steps are split → fit → predict → calculate RMSE. Put those same steps into a function. Its inputs are the data and training-row numbers; its output is one RMSE:
holdout_rmse <- function(data, train_rows) {
  train <- data[train_rows, ]
  validation <- data[-train_rows, ]
  model <- lm(y1 ~ x1, data = train)
  predicted <- predict(model, newdata = validation)
  error <- validation$y1 - predicted
  sqrt(mean(error^2))
}

holdout_rmse(anscombe, train_rows)
## [1] 1.650601
Repeat and summarize
Choose eight of the eleven rows for training in each of 100 runs. Sampling is without replacement within a run. The remaining three rows are used for validation; across runs, the same observation may be held out several times.
Set the seed once before sampling. Keep the training-row list so each split can be reconstructed; its first element is run 1, its second is run 2, and so on.
set.seed(6)
training_rows <- lapply(1:100, function(i) {
  sample(nrow(anscombe), 8)
})

rmse <- unlist(lapply(training_rows, function(rows) {
  holdout_rmse(anscombe, rows)
}))
Each function call returns one score. Summarize the resulting vector directly:
mean(rmse)
## [1] 1.279602
sd(rmse)
## [1] 0.5016735
hist(rmse, xlab = "RMSE per run", main = "100 random holdout runs")
abline(v = mean(rmse), col = "red", lwd = 2)
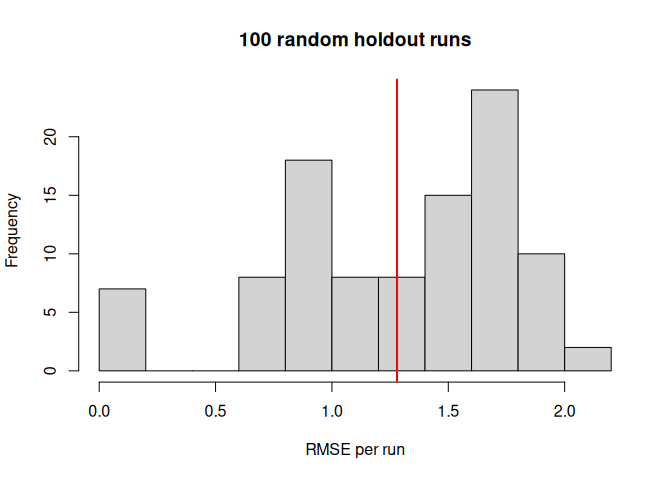
Take home: the mean summarizes the run-level prediction errors; the SD describes how they vary between splits. Because runs reuse observations, this SD is not a standard error or confidence interval for performance on new data.
Four-fold cross-validation
Four-fold cross-validation ensures that each observation is held out once per complete run. First assign the rows to four approximately equal groups. rep(1:4, length.out = ...) repeats the four labels to match the number of rows; sample() shuffles them:
set.seed(7)
fold <- sample(rep(1:4, length.out = nrow(anscombe)))
table(fold)
## fold
## 1 2 3 4
## 3 3 3 2
Start with an empty prediction vector. For each fold, fit on the other rows and put its predictions into the corresponding positions:
predicted <- rep(NA, nrow(anscombe))
for (k in 1:4) {
  train <- anscombe[fold != k, ]
  validation <- anscombe[fold == k, ]
  model <- lm(y1 ~ x1, data = train)
  predicted[fold == k] <- predict(model, newdata = validation)
}
All rows now have one held-out prediction. Calculate the RMSE from all their errors together:
error <- anscombe$y1 - predicted
sqrt(mean(error^2))
## [1] 1.472177
Take home: a complete four-fold run gives one RMSE, calculated from all held-out errors together. Do not average four separate fold RMSEs. To compare candidate models in Unit 07, keep the same observations and fold assignment for every candidate.
Exercise: One validation run
Allow 15 minutes. Using the same Anscombe data, fit on rows 1–7 and predict the remaining four rows. Calculate their RMSE, then check your result with holdout_rmse(). Work through the individual steps before using the function.
Explain which rows were used for fitting and why this gives one RMSE. Would the difference from the earlier eight-row training example establish that seven training observations are generally better or worse? Discuss your answer; no separate submission is required.
Transfer to the regional data
For Assignment 06, repeated random holdout is the simplest starting point. Choose and document a training fraction, such as approximately 80%. Repeated complete folds are also valid: they ensure every observation is evaluated once per run. One leave-one-out run alone does not provide the requested distribution across runs.
Reuse Assignment 05’s 2014 district-level cohort with complete Agriculture–Forest pairs. Keep the region IDs in the data and retain the split indices, as in the training-row list above. For fold-based runs, keep each run’s fold vector instead. This identifies the observations in each run without creating a separate prediction-record table.
These random splits assess other records within this historical cohort. Nearby districts can still be related. Predicting unseen regions needs an appropriate geographic grouping; predicting future years needs chronological validation. Do not mix repeated years or nested administrative aggregates with their component districts. A random split alone does not remove spatial or temporal dependence.
Further watching
For a written description of fold partitioning, see the R documentation for cross-validation. The worked analysis uses base R.