Example: Generalized Additive Models
A generalized additive model (GAM) represents a response using a sum of predictor effects, which can include smooth functions. Here we fit a smooth mean curve for a continuous response: y = intercept + s(x) + error. We use normally distributed errors and keep predictions on the response’s original scale.
A straight line is still possible: supplying y ~ x to mgcv::gam() does not add a smooth automatically. We will compare that linear fit with penalized and unpenalized smooths, then distinguish curve fitting, tuning and independent evaluation.
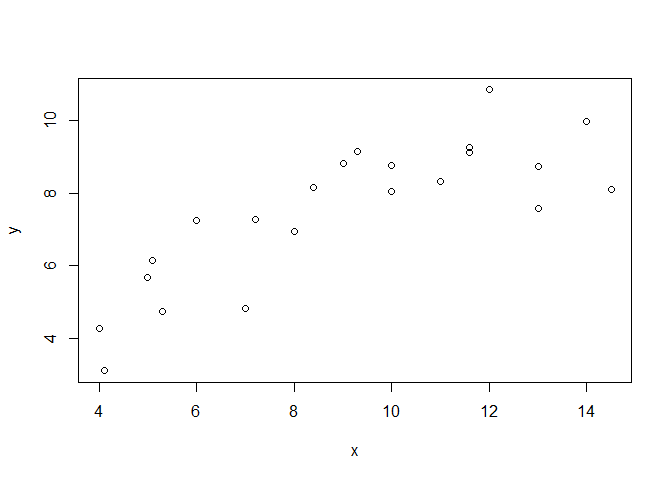
Download gam-example.csv into Data/. This is the existing 22-row illustration combining the first and second Anscombe datasets, with the second predictor slightly perturbed. The prepared file avoids extra setup. We use it to compare fitted curves, not to claim reliable predictive performance.
mgcv supplies the GAM fitting method needed here; the remaining analysis and plots use base R.
library(mgcv)
df <- read.csv("Data/gam-example.csv")
plot(df$x, df$y)
Record the software versions when reproducing model summaries:
c(R = as.character(getRversion()),
  mgcv = as.character(packageVersion("mgcv")))
##       R    mgcv
## "4.3.3" "1.9.1"
From linear regression models to generalized additive models
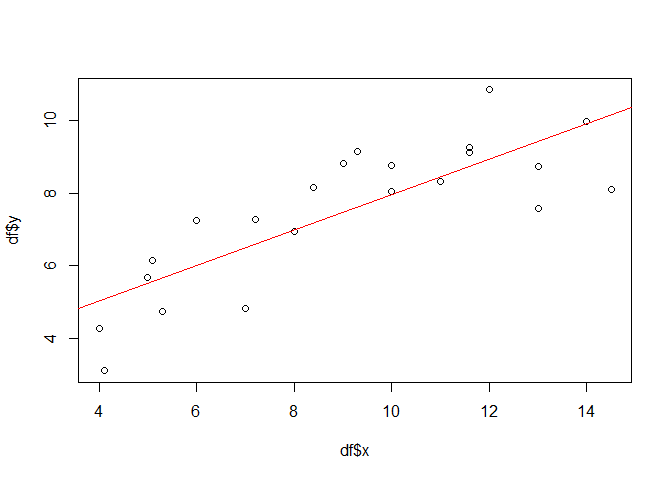
First fit a straight line to the combined observations:
plot(df$x, df$y)
lmod <- lm(y ~ x, data = df)
abline(lmod, col = "red")
summary(lmod)$r.squared
## [1] 0.6567026
The R squared in this summary describes training fit. It does not measure prediction on observations held out from fitting.
Using gam(y ~ x) would fit the same straight line. To allow a curve, add the smooth term s(x).
Two controls determine the curve’s flexibility:
k(basis dimension) limits how complex the curve can be; it is not a literal number of knots.fx = FALSElets fitting penalize unnecessary wiggles within that limit.fx = TRUEremoves that penalty, so the chosenkcontrols complexity directly.
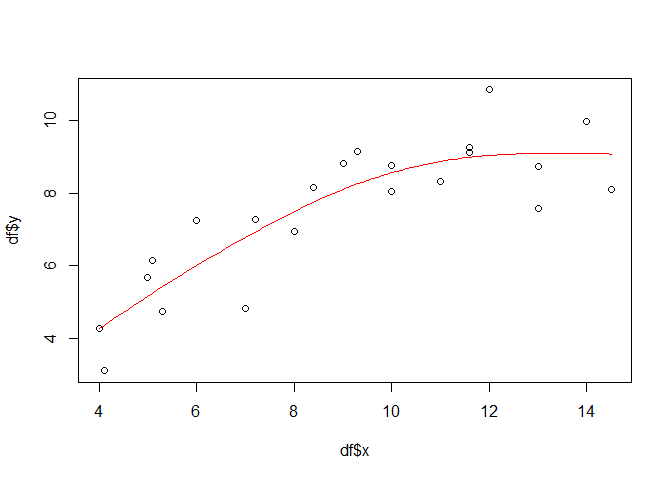
Start with k = 10. By default, fitting chooses a penalty strength from the training data. Draw the fitted response on an ordered grid px, using newdata as in Unit 06:
px <- seq(min(df$x), max(df$x), length.out = 200)
smooth_gam <- gam(y ~ s(x, k = 10), data = df)
gampred <- predict(smooth_gam, newdata = data.frame(x = px))

plot(df$x, df$y)
lines(px, gampred, col = "red")
summary(smooth_gam)$r.sq
## [1] 0.7511845
summary(fit)$r.sq returns adjusted training R², accounting for fitted complexity. It can be negative and is not a held-out score; see the GAM summary documentation. The residual checks from Unit 05 still matter: a smooth curve does not automatically fix changing spread, unusual residuals or dependence.
Take home: s(x) allows a curved relationship; a closer training fit alone does not establish better prediction.
Optimal smoother selection and reducing the risk of overfitting
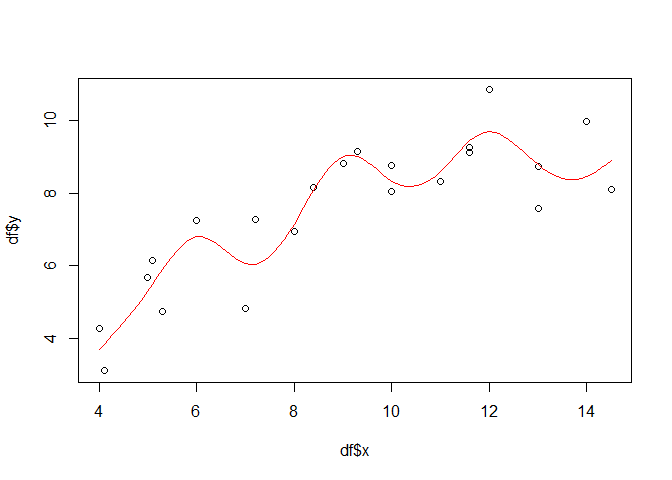
Overfitting means following chance features in training data that do not help prediction. Compare the penalized curve above with an unpenalized fit using the same k = 10:
fixed_gam <- gam(y ~ s(x, k = 10, fx = TRUE), data = df)
gampred <- predict(fixed_gam, newdata = data.frame(x = px))

plot(df$x, df$y)
lines(px, gampred, col = "red")
summary(fixed_gam)$r.sq
## [1] 0.7400548
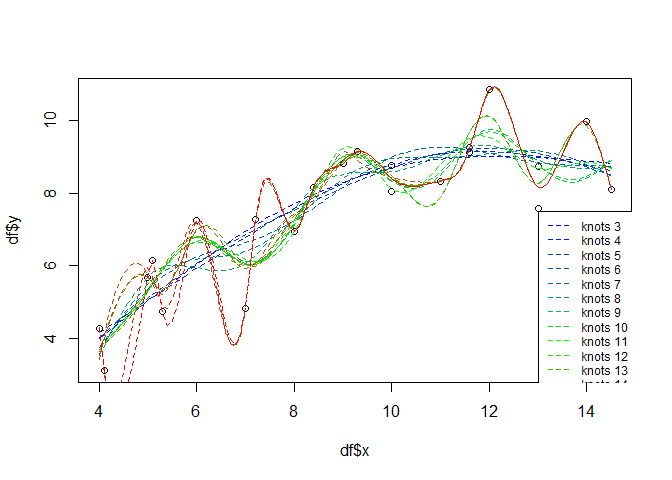
Closer agreement with training data can accompany worse held-out prediction. Adjusted training R squared also accounts for fitted model complexity, so it can decrease even when the fit to the training observations becomes closer.
For an explicit basis-size tuning exercise, vary k with fx = TRUE. The next plot only compares fitted curves; it does not select a model by validation. This toy dataset has 22 rows and 19 distinct predictor values, so the illustrative range stops at k = 19. At that upper end, only three residual degrees of freedom remain. Feasibility depends on the training subset, not just the full dataset.
basis_dimensions <- c(3, 9, 19)
cols <- c("black", "blue", "red")
curve_predictions <- lapply(basis_dimensions, function(k) {
  fit <- gam(y ~ s(x, k = k, fx = TRUE), data = df)
  predict(fit, newdata = data.frame(x = px))
})
plot(df$x, df$y, ylim = range(c(df$y, unlist(curve_predictions))))
for (i in seq_along(basis_dimensions)) {
  lines(px, curve_predictions[[i]], col = cols[i], lty = i)
}
legend("topleft", legend = paste("k =", basis_dimensions),
       col = cols, lty = 1:3, cex = 0.9, bty = "n")
From curve fitting to tuning
Use held-out prediction errors to compare tuning settings. Keep the observations and validation partitions fixed across candidates, as in Units 06–07. To show the distinction from final evaluation, create a larger independent synthetic sample. runif() draws predictor values uniformly between −2 and 2; sin() supplies a curved mean and rnorm() adds normal random error. Reserve 20 observations as a final test set; split the remaining 80 into 60 for fitting and 20 for tuning:
set.seed(808)
tuning_data <- data.frame(x = runif(100, -2, 2))
tuning_data$y <- sin(2 * tuning_data$x) + rnorm(100, sd = 0.25)

training_id <- sample(nrow(tuning_data), 60)
remaining_id <- setdiff(1:nrow(tuning_data), training_id)
validation_id <- sample(remaining_id, 20)
final_test_id <- setdiff(remaining_id, validation_id)
train_data <- tuning_data[training_id, ]
validation_data <- tuning_data[validation_id, ]
final_test <- tuning_data[final_test_id, ]
First fit one setting, k = 3, and predict the 20 validation responses. Calculate its adjusted training R² and held-out RMSE separately:
fit_k3 <- gam(y ~ s(x, k = 3, fx = TRUE), data = train_data)
pred_k3 <- predict(fit_k3, newdata = validation_data)
summary(fit_k3)$r.sq
## [1] 0.09242067
sqrt(mean((validation_data$y - pred_k3)^2))
## [1] 0.7751167
Now repeat the fitting step for three settings on the same training rows. Then predict the same validation rows and calculate one RMSE for each model:
candidate_k <- c(3, 5, 9)
models <- lapply(candidate_k, function(k) {
  gam(y ~ s(x, k = k, fx = TRUE), data = train_data)
})
predictions <- lapply(models, function(model) {
  predict(model, newdata = validation_data)
})
rmse <- unlist(lapply(predictions, function(predicted) {
  sqrt(mean((validation_data$y - predicted)^2))
}))
adjusted_r2 <- unlist(lapply(models, function(model) {
  summary(model)$r.sq
}))
data.frame(k = candidate_k, Training_adjusted_R2 = adjusted_r2,
           Validation_RMSE = rmse)
##   k Training_adjusted_R2 Validation_RMSE
## 1 3           0.09242067       0.7751167
## 2 5           0.86031070       0.3130160
## 3 9           0.85346151       0.3220130
Take home: fit → predict → score, keeping the same observations for every setting.
Exercise: Compare two settings
Allow 15 minutes. Fit k = 5 on train_data, predict validation_data and calculate its RMSE. Compare it with the k = 3 example, including adjusted training R². Explain which score you would use to choose a setting and why a better training fit need not win. Leave final_test unused; no separate submission is required.
Keep final evaluation independent
Select the smallest validation RMSE, keeping full precision for the comparison. The minimum is a tuning score, since it helped choose k. Freeze that choice, refit on the 80 development observations, and use the reserved test set once:
selected_k <- candidate_k[which.min(rmse)]
development <- rbind(train_data, validation_data)
final_gam <- gam(y ~ s(x, k = selected_k, fx = TRUE),
                 data = development)
final_prediction <- predict(final_gam, newdata = final_test)
final_test_RMSE <- sqrt(mean((final_test$y - final_prediction)^2))
c(selected_k = selected_k, final_test_RMSE = round(final_test_RMSE, 3))
##      selected_k final_test_RMSE
##            5.00            0.22
plot(final_test$y, final_prediction, xlab = "Observed final-test response",
     ylab = "Final-test prediction", asp = 1)
abline(0, 1, col = "red")
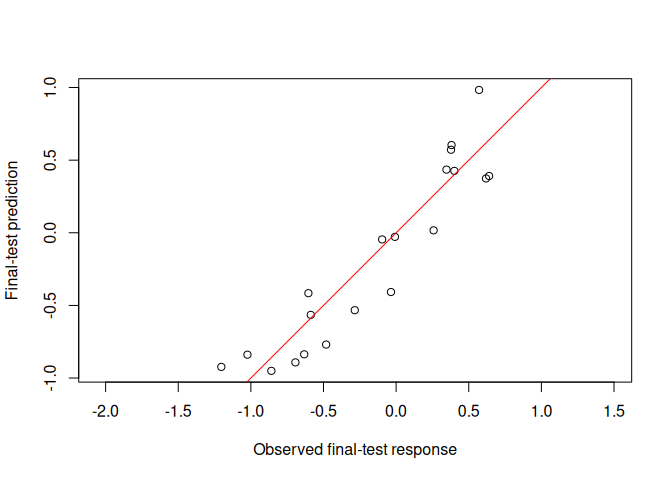
Take home: choose the setting with validation data, freeze it, then evaluate it with the final test data. Using that final score to revise the choice would make the test part of tuning. Repeated tuning splits belong within the development data.
Metrics for repeated tuning runs
For each candidate k and each tuning run, retain one held-out RMSE and the fitted model’s adjusted training R squared. The three curves requested in Assignment 08 have these definitions:
| Curve | Calculation for each k |
Interpretation |
|---|---|---|
| Mean RMSE | Mean of the 100 run-level held-out RMSE values. | Average error across the chosen random splits; smaller is better. |
| Mean RMSE ± SD | Mean RMSE plus/minus the SD of those same 100 run-level values. | Descriptive sensitivity to the splits, not a standard error or confidence interval. |
| Mean training adjusted R squared | Mean of summary(fit)$r.sq across the 100 training fits. |
A fitted summary, not a held-out prediction score; it can be negative. |
Repeat the one-run pattern from Unit 06 on the same saved splits for every k. Summarize its RMSE vector with mean() and sd(). These runs reuse observations; the SD describes sensitivity to the splits.
For a shared-scale plot, calculate one divisor: the maximum mean RMSE across the candidate settings. Divide the mean RMSE and both SD bounds by that same divisor; keep adjusted R squared on its own scale. Label the normalization and retain the original error units when reporting numerical values. The scaled error is unitless, but its height is not equivalent in meaning to R squared. Set axis limits to show every curve, including negative adjusted R squared or a descriptive lower SD bound below zero.
Annual observations in Assignment 08
The timber dataset has only 23 annual records, from 2003 to 2025. The assignment retains 100 random 80/20 splits: 18 training years and five held-out years per run after rounding down the training size. Its target is retrospective prediction of held-out records within the same historical series, not forecasting a future year. Shared trends, serial dependence and collection changes can make random-split scores optimistic. A held-out predictor value can also lie outside the training predictor range; inspect that possibility rather than treating every random split as interpolation.
For this unpenalized model with one smooth, k cannot exceed the number of distinct training predictor values, and the number of fitted coefficients must leave residual degrees of freedom. The current complete timber input has 23 distinct oak-harvest values, so every 18-year training set can support k = 3:13; the largest candidate uses 13 model coefficients including the intercept and leaves only five residual degrees of freedom. Being estimable does not make that setting reliable. Keep all candidates on the same 100 splits; report and diagnose failures rather than silently comparing different sets of successful runs.
This is a tuning exercise. Its best repeated-split score has already been used to choose k; do not present it as an independent final performance assessment. A separate final-test submission is not required. Chronological or blocked validation would address a different prediction design and needs a separate choice of training windows and feasible basis sizes.